Day 35

Infrastructure as code: Terraform and deployment targets

You ship
WorkBot's infrastructure as Terraform on 3 targets, through a plan, review and apply pipeline, with a demonstrated rollback.

What you'll build today

After Day 34, WorkBot runs as two container images and a database, and its deployments are written as steps for a person to type. Today you turn those steps into code that a machine applies, so the deployment can be repeated, reviewed and rolled back.

You write the infrastructure as Terraform, a tool that creates cloud resources from configuration files, for three targets. They are Cloud Run on Google Cloud, a Kubernetes cluster, and an Azure virtual machine (VM). WorkBot becomes a Helm chart, the package format of Kubernetes. You add releases that migrate, test and roll back, and a pipeline that runs them.

The Kubernetes target runs for real on a local cluster that stands in for a clean account, where you release it, scale it, roll it back and recreate it. Google Cloud and Azure are planned in tests against mocked providers, since applying them bills an account. By the end, connecting a real account means setting a few variables, not writing code.

Three targets
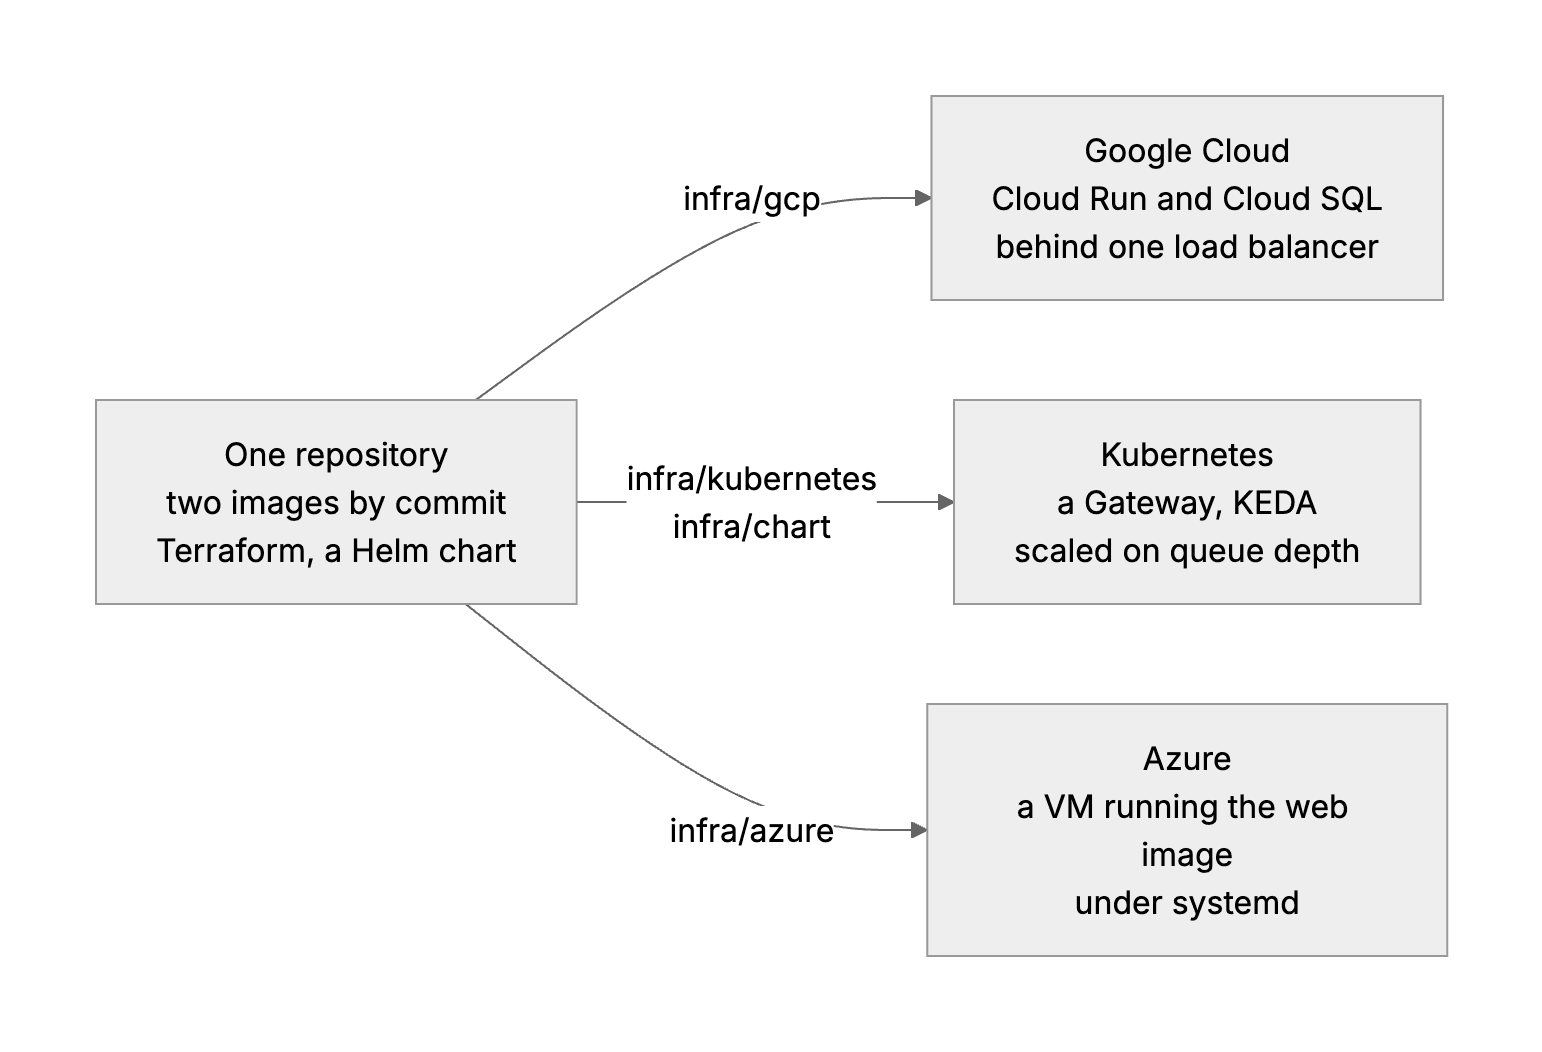
One repository and two images serve three targets: Cloud Run with Cloud SQL, a Kubernetes cluster scaled on queue depth, and an Azure VM behind a load balancer.

By the end of the day you can

  • Define your infrastructure in Terraform and reproduce it from scratch, in a new account or on a local cluster that stands in for one
  • Target managed containers (Cloud Run or ECS on Fargate), Kubernetes and an Azure VM, and know what each is for
  • Run deployments through CI with plan, review and apply

Topics

Terraform Fundamentals

  • Building blocks: providers, resources, data sources, variables, outputs
  • State, Terraform's record of what it created: remote and locked, always
  • Modules: one per unit created more than once (a service, a database, a queue)
  • Plan, apply, destroy. Read a plan before approving it, and detect drift
  • Environments: workspaces or directories, never one state for everything
  • Secrets: what ends up in state, and how to keep keys out of it

Containers Everywhere

  • One image for API and workers, with different commands. Multi-stage builds, health checks and read-only filesystems
  • Registries per cloud, tagging by commit, and promotion from staging to production by tag

Deployment Targets

  • ECS on Fargate: tasks and services, autoscaling on queue depth or CPU, and no nodes to manage. It is the default on AWS
  • Elastic Beanstalk: platform-managed environments for a single web application, and where it still fits
  • Kubernetes (Amazon EKS, Google GKE): deployments, services, ingress or the Gateway API that replaces it, horizontal pod autoscaling, secrets and config maps. Weigh the operational cost, and when a customer requires it anyway
  • Azure VMs: a hardened image, a systemd service and a load balancer in front, with Container Apps as the managed alternative
  • Choosing: managed containers first, Kubernetes when the customer's platform team runs it, VMs when policy demands it

Delivery Pipeline

  • CI: build and test, build the image, push it
  • Continuous delivery (CD): terraform plan on each pull request, apply on merge with approval, deploy the tag, run smoke evals, and roll back on failure
  • Migrations: forward-only, run before the new version serves traffic
  • Parity: the same modules for staging and production, with different variables

Build

Features shipped today

  • WorkBot: Infrastructure as Terraform on 3 targets (Cloud Run, Kubernetes and an Azure VM), through the pipeline. The neo-cloud deployment stays as the Day 34 steps

Make the Day 34 deployment reproducible and portable:

  1. Terraform for the GCP (or AWS) deployment: network, database, secrets, container service and load balancer. Keep the state remote and locked, write one module per unit, and make staging and production from the same modules
  2. Prove it: destroy the environment and recreate it from nothing with one command sequence, and time it. A local cluster can stand in for a clean account
  3. Second target: the same images on a Kubernetes cluster (EKS, GKE, or kind on your machine) with deployments, a service, a Gateway and autoscaling on queue depth
  4. Third target: an Azure VM running the API as a systemd service behind a load balancer, provisioned by Terraform. Without a subscription, check it with a mocked plan and run its container locally
  5. Pipeline: plan on each pull request, apply on merge with manual approval, deploy by tag, smoke evals, and automatic rollback
  6. Keep the evidence linked from the runbook: the timed recreation from nothing, the same images running on Kubernetes, and the rollback

Step by step

Choose the targets

The three targets cost the customer's team different amounts of work, so first decide what each one is for. That choice tells you which target a given customer should get.

Study first

  • The deployment targets differ in what each costs to run. Amazon ECS (Elastic Container Service) on Fargate or Cloud Run gives managed containers with no nodes, and Elastic Beanstalk runs one web app on a platform-managed environment.
  • Kubernetes on Amazon EKS (Elastic Kubernetes Service) or Google GKE (Google Kubernetes Engine) gives deployments, services, ingress and autoscaling, and needs a platform team to run it. A VM needs a hardened image, a systemd service and a load balancer.
  • The order of preference is managed containers first, Kubernetes when the customer's platform team runs it, and a VM when policy demands one.
  • AWS's guide to choosing a container service sets out the same trade-off on one cloud, with the skills and upkeep that Kubernetes asks of a team.

Build

  1. Write a table in docs/infrastructure.md of the three targets, with what each is for, where its code is, and how it was proven.

Done when

  • You can say which target a given customer gets, and what the next one down would cost their team.
Terraform for Google Cloud

Google Cloud is the default target, so its Terraform comes first. Staging and production share one root, which keeps their differences small and easy to check.

Study first

  • Terraform's building blocks are providers, resources, data sources, variables and outputs, and its commands plan, apply and destroy. Read a plan before you approve it.
  • State, Terraform's record of what it created, is remote and locked, one per environment. Write a module for a unit made more than once.
  • Know what ends up in state, and the two ways to keep keys out of it. One is ephemeral values with write-only arguments, which Terraform uses during a run but never stores. The other is secrets that Terraform creates empty.

Build

  1. Write infra/gcp, which holds Cloud SQL on a private address, Secret Manager and the registry. It makes the web and realtime services from one module, infra/modules/cloud-run-service, and puts a load balancer in front that serves /realtime on the app's host.
  2. Make staging and production from the same root, with staging.tfvars and production.tfvars. Give each a state under its own prefix in one bucket, which is the one thing made by hand before Terraform runs.
  3. Make the database password an ephemeral value, written through password_wo and secret_data_wo, while the API keys never pass through Terraform at all.
  4. Write a Terraform test, run by terraform test, that plans both environments against a mocked provider and asserts the differences. Only production has a standby and deletion protection. Neither environment's database has a public address, and the password is absent from the plan.

Done when

  • Both environments plan from the same code with only the differences you meant, and no secret appears in a plan.
Technical notes
  • Services start on Google's placeholder image, and Terraform ignores the image and command after that. A first apply then needs no image in the registry, and releases own what runs.
  • infra/gcp/release.sh runs the migration and the smoke suite as Cloud Run jobs with the new tools image first. Then it moves both services, and it restores both revisions if either fails.

Package the app for Kubernetes

Kubernetes needs two layers, the cluster's platform and the app on top of it. Terraform installs the platform, and a Helm chart installs the app, so each can change on its own schedule.

Study first

  • Learn Kubernetes deployments, services, secrets and config, and horizontal autoscaling. The Gateway API replaces Ingress, now that ingress-nginx is retired. KEDA (Kubernetes Event-driven Autoscaling) scales on an external metric.
  • Learn how Helm uses charts, values, hooks and tests.

Build

  1. Write infra/kubernetes, which Terraform applies to install the Gateway API's resource types, Traefik to serve them, KEDA, the namespace, and the secrets through write-only arguments. Keep its state in Postgres outside the cluster, locked.
  2. Write infra/chart, where every service comes from one template that loops over values.yaml. It includes Postgres for a cluster that stands alone, and a Gateway with the realtime server under /realtime.
  3. In the chart, add a ScaledObject that scales on the documents waiting to be read. Run the migration as a hook, and the eval smoke suite from Day 25 as helm test.
  4. Install the chart on a kind cluster, a local Kubernetes cluster that runs in Docker, and fix what breaks.

Done when

  • A release on an empty namespace installs, migrates and passes every eval gate inside the cluster, where an eval is a scored test of WorkBot's output.
Release
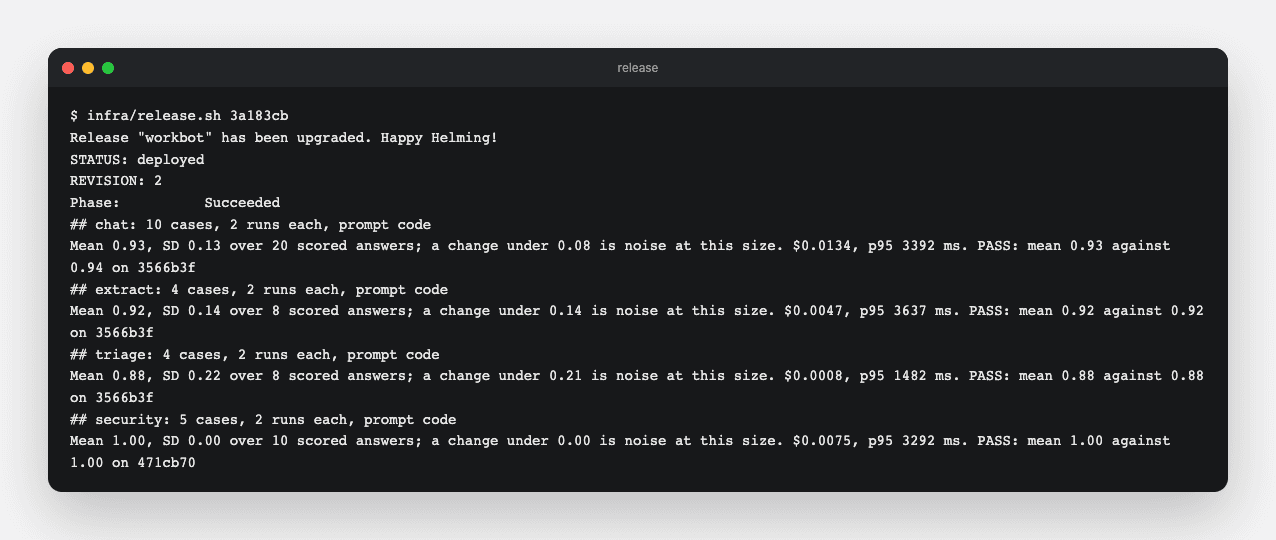
A release through the Gateway installed, migrated and passed the eval smoke suite in the cluster.
Technical notes
  • Set enableServiceLinks: false on every pod, because Kubernetes sets a variable per service. The inngest service gave every pod INNGEST_PORT=tcp://…, which Inngest read as its port.
  • Run the images as user 1000, because runAsNonRoot cannot verify a user given by name.
  • Try the database connection again after a failure. In the reference run, the web pod's first query ran before Postgres was ready, and the failed connection was cached for every query after. Compose had hidden it by starting the database first.
  • KEDA reads the queue from its own namespace, so give it the database service's full name as the address.
  • The Gateway API's resource types are too large for a Helm release, which Helm stores in one Secret of at most 1 MiB. So Terraform applies the project's manifest directly.

Scale on queue depth

On the cluster, the web tier can grow with the work waiting for it. The right signal for that growth is the queue, because the workers spend their time waiting on a model.

Study first

  • For a worker that waits on a model, the backlog is the signal to scale on, not CPU. KEDA's Postgres scaler scales on the number a SQL query returns, against a target per replica.
  • KEDA hands the scaling itself to the Kubernetes horizontal pod autoscaler, which waits through 5 minutes of lower readings before it scales down.

Build

  1. Add a KEDA trigger that counts the inbox rows still received, and runs one web replica per 20, from 1 to 4. The web tier is the worker, because Inngest calls it for each step.
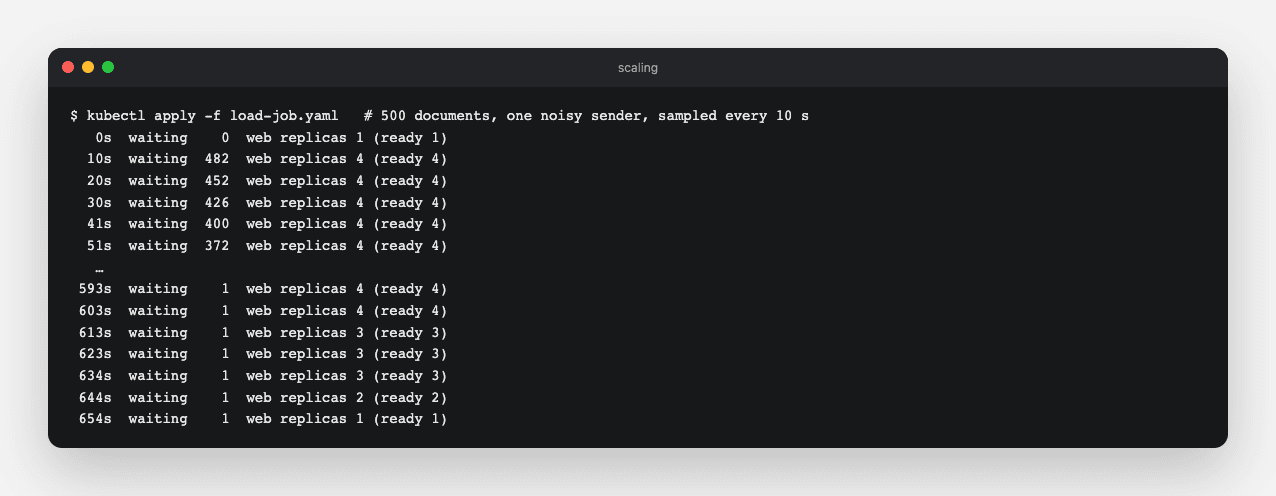
  2. Run the 500-document load test from Day 33 as a Job in the cluster, and watch the replicas.

Done when

  • The web tier scales out while documents wait, and returns to one replica when the queue is empty.
Scaling
In the reference run, 482 documents waiting brought 4 web replicas within 10 s, and the tier went back to one replica about 5 minutes after the backlog cleared. One document stayed waiting, an open item in docs/infrastructure.md.
Technical notes
  • Inngest runs at most 10 steps at once, so replicas past that add nothing, and you set the cap and the maximum together.
  • With a minimum of one replica, KEDA hands scaling down to the autoscaler, which waits for 5 minutes of low readings before it removes pods.

Release, roll back and recreate

A release must never leave the app broken, and the whole environment must be repeatable. This part tests both, first with a broken release and then with a rebuild from nothing.

Study first

  • Promotion by tag means you build one image per commit and release it to staging and then production unchanged. The Twelve-Factor App's build, release, run factor gives the reason, since a release is a build plus its config, with an id you can roll back to.
  • Migrations go forward only, and run before the new version serves traffic. Helm runs them as a pre-upgrade chart hook, after the templates render and before any resource changes, and a failed hook fails the release.

Build

  1. Write infra/release.sh <tag>. It runs a Helm upgrade that migrates first and waits for the new pods, and restores the previous release if they never become ready. Then it runs helm test, and rolls back if the test fails.
  2. Release a good tag, then a broken one whose web container exits at once.
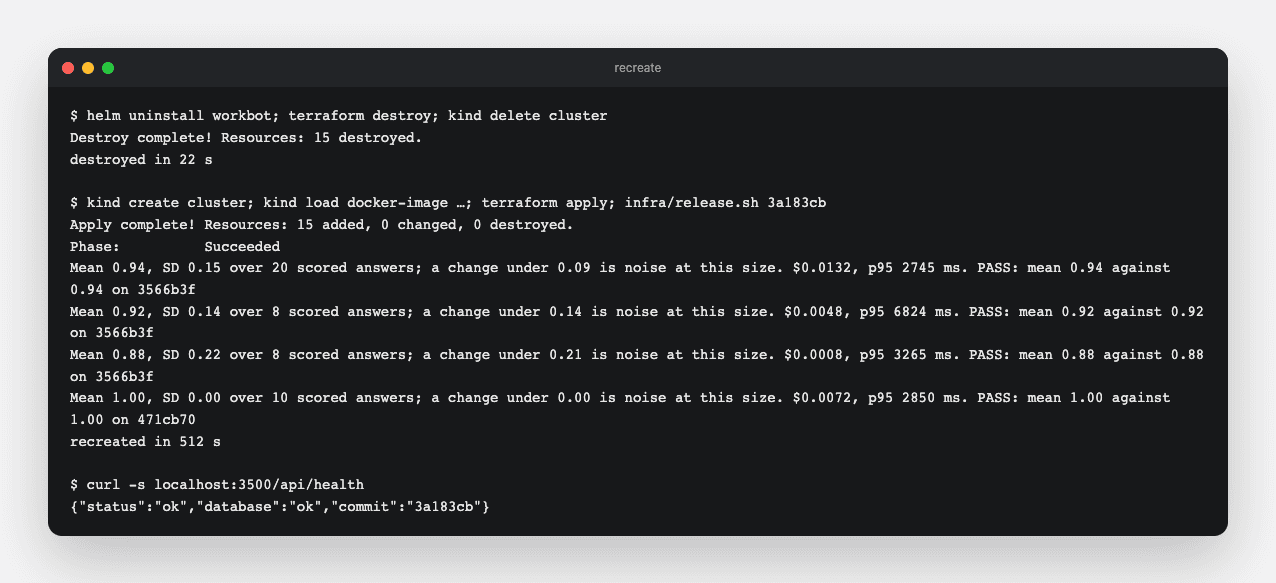
  3. Destroy the environment, meaning the release, the platform and the cluster. Then make it again with one sequence: create the cluster, load the images, apply the platform, and release the tag. Time both the destroy and the recreate.

Done when

  • The broken release never takes traffic, and the history shows the previous release restored.
  • The app answers through the Gateway on the new cluster, and you know how long the sequence takes.
Rollback
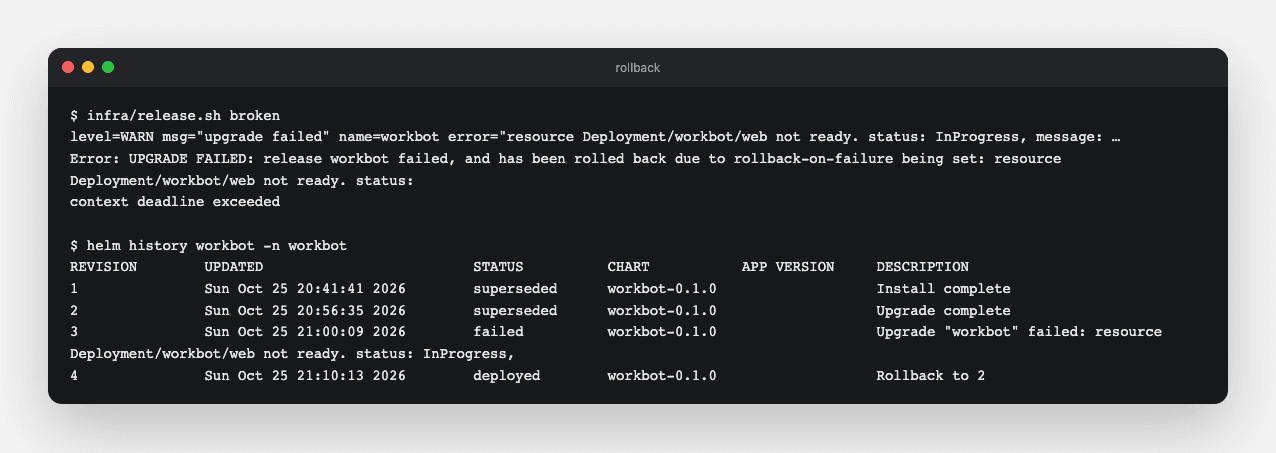
The broken tag's pods never became ready while the old ones served, and Helm restored revision 2.
Recreated
The environment is destroyed and recreated from nothing, timed, and ends with the health check through the Gateway.

Provision the Azure VM

Some customers allow only virtual machines that they harden themselves. In the reference run, the VM's own setup was checked locally but not on Azure, and you can check it the same way without a subscription.

Study first

Build

  1. Write infra/azure. It makes a network with no SSH rule, a load balancer probing /api/health, an outbound rule, and an Ubuntu VM with its own identity.
  2. Write the cloud-init file, which installs Docker and a unit that runs the web image read-only, with every capability dropped. A script reads the keys from Key Vault into memory.
  3. Check it without a subscription by running a mocked plan, then cloud-init schema and systemd-analyze verify on Ubuntu 24.04. Run the unit's own docker run line against Postgres.

Done when

  • The unit's container serves health read-only as user 1000, and the plan admits nothing but the app's port.

Run it through a pipeline

The pipeline runs these checks and releases on every change, with a reviewer in front of anything that touches production. It is the reason connecting an account later needs no new code.

Study first

  • Plan on a pull request, apply on merge behind a reviewer, deploy the tag, run the smoke suite, and roll back. Use workload identity federation instead of stored cloud keys, so the pipeline signs in to the cloud without a key kept in GitHub.

Build

  1. Write .github/workflows/infra.yml. On every pull request that touches infra/, it formats and validates every root, runs the mocked tests where a root has them, and lints the chart.
  2. Once Google Cloud is connected by four repository variables, the pull request also shows the real plan. A merge then applies it in the production environment, which is configured to wait for a reviewer.
  3. Write .github/workflows/release.yml. A v* tag builds the two images and runs the release script of each connected target, Cloud Run or a cluster.

Done when

  • The checks pass on the pull request without an account, and connecting one means setting variables, not writing code.

Resources