The enterprise AI diffusion gap is about human expertise
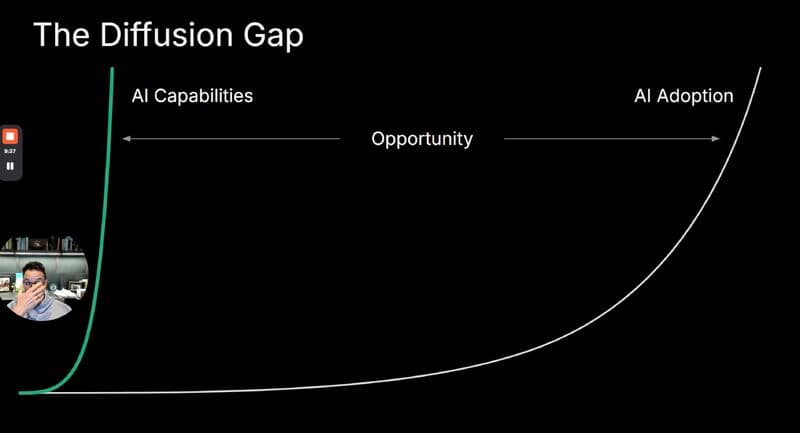
The diffusion gap Pat from Sequoia is talking about is real! Model capabilities are already sufficiently advanced for most enterprise use cases. The gap is the human expertise to interface with the humans on the other side. This requires a new type of organization to deliver this capability, totally new types of skills and roles, and a new type of software delivery process. It has been exciting to think about all this here at Plank and work closely with our customers to close this diffusion gap for them.
Listen to Pat's notes: loom.com/share/c016702964a04dfba40e1777cf5f053a
- Forward deployed engineering
- Enterprise AI
Keep reading
Newer: IIT Delhi makes core computer science courses optionalModels and research
Missing discrete math and the pigeonhole principle
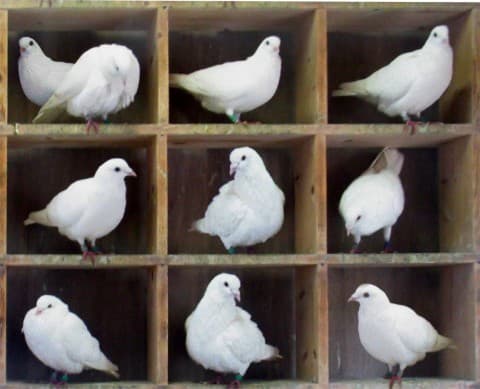
I miss Discrete Math - it was a subject that invoked an emotional feeling of symmetry, that everything is in it's place and fits. One obvious, yet beautiful and powerful theorem was the PigeonHole Principle. It states that if n items are put into m containers, with n > m, then at least one container must contain more than one item. While it's obvious, it can be used to demonstrate some unexpected results...Eg, given that the population of London is more than one unit greater than the maximum number of hairs that can be on a human head, the principle requires that there must be at least two people in London who have the same number of hairs on their heads. The more advanced probabilistic versions of this can be used to derive some really non-obvious statistical correlations or conclusions. en.wikipedia.org/wiki/Pigeonhole_principle
Enterprise AIModels and research
Enterprise token costs head to zero, research costs grow
One thing that struck me was that while enterprise AI token costs will converge to zero because of the predictability of workflows, consumer AI usage costs will in fact go the other way because each consumer has a unique context, and further each conversation is unique. In research domains like biology, medicine, robotics, these would go up! So - enterprise token costs -> zero - consumer token costs -> stay steady - research domain token costs -> grow
Enterprise AISoftware architecture
Enterprise AI starts in the business domain, not technology
In my recent travels, as I was reflecting on enterprise AI deployments, I realized that true beauty and elegance is in unpacking the problem from the business domain to the product domain and only then the technical domain. Most enterprise AI attempts today start from technology first - pre-AI-era vendors trying to shoehorn their technology with AI slapped on top, selling complexity and "big data". In our experience even with large F500 companies, these are almost always never big data problems - my favorite quote is I can run this analysis on my iPhone, why are you running this big data lake with large compute clusters crunching data that is never actually used. Remember 100s of millions of data points are small numbers for computers! The magic is in understanding what to solve and the modeling of the business problem with an elegant technical design. If you do that, you don't need complex industrial grade pre-AI bloatware.
AI agentsEnterprise AI
A new security category to keep AI agents from going rogue
I foresee the emergence of a new category of security companies that offer guarantees that your agent will not go rogue in a way like what happened to the OpenAI agents hacking HuggingFace. Specially for enterprise deployments, this will become an essential layer in the agent architecture that ensures this. Curious if anyone is building in this space?
Models and research
Local models will soon be mainstream on consumer devices
In the small models vs cloud models debate, we're overlooking the fact that consumer hardware devices are still only at the cusp being ready for running these models locally. Even Apple MacBooks, phones are not quite there yet. But my guess is that within a year, we will reach that point. And yes we will always live in a hybrid world of local and cloud models, but local models will become a mainstream part of consumer device operating systems.
Software architecturePlank
Why Plank relies on humans for system design
Here at Plank we believe in relying on humans for coming up with product plans, system designs and core architecture. Being able to bring together business, product and engineering perspectives and getting to the gist of things is something AI still needs more training on. Plans created by AI are often over-engineered, generic and miss out on the magic often. It is ok to provide the detailed plan to AI and let it explore some options or propose language alternatives to communicate. We foresee this to be an increasingly rare skill going forward. An early example of this is Ernst & Young awarding $100 million in bonuses to workers who demonstrate human skills, such as leadership, judgment, business acumen, collaboration and an ability to adapt. An easy way to make sure you don't lose your way is keeping an invariant that you always need to have a block diagram and information flow of whatever system you are building in your mind.
Enterprise AIPlank
The SaaS business model is unraveling in enterprise HR
At Plank, we are seeing first hand the unraveling of the SaaS business model. Large F500 as well as mid-market customers are coming to us to move away from expensive SaaS HR solutions that are rigid, built in a pre-AI world and very slow to work with for changes. In our experience, we are able to build completely custom solutions that are deployed in customer's cloud, with fully local and private LLM under the hood and with full IP owned by them; all in a matter of weeks. So they are comparing solutions that are 8-figure annual costs with a multi-year implementation with just a 6-week implementation and very low one-time implementation costs with close to zero on-going maintenance costs. Also the solution is built in an AI-native way using the latest approaches. Since these techniques were just developed in the last 6-months, existing incumbents simply are not architected in this way.
Coding agentsModels and research
A 3-layer model architecture for agentic coding workloads
In our experiments, we found that using open source models like Qwen or Deepseek via OpenRouter looks temping and cheap on a per call or $/tokens. However, if you run a real benchmark with your pull requests, these models end up taking more rounds before they converge when running agentic workloads. The way to go is to deploy your own open source models. The architecture we go with is a 3-layer one. The 1st layer is local models running on developer machine, the 2nd layer is open source models deployed in our own cloud servers and the 3rd layer is the latest models offered by the labs. We also are able to distribute the workload based on the type - eq a pull request review can run on a slower machine as its not sync.