Stop building traditional RAG and let the agent do it
Anyone who is building RAG in a traditional way today should STOP and revisit approach. Unless you have millions of documents with terabytes of data, you can get a much better result by using Agent SDK and giving it access to the docs and letting it do the RAG. The agent would be able to analyze the docs, classify/index them and figure out what it needs to bring into the main context.
Over the past 2 years, I have seen very strange uses of RAG. Eg companies that were trying to do a RAG on a single document, doing RAG on a database with structured types (non-text data), etc.
TBH, with the recent improvements in Claude and Codex, and long-running agents, there is very little reason to build a complex agent architecture in the app layer. The best approach is to specify very clearly and succinctly your goals at the highest abstraction layer and just getting out of the way of the model.
- AI agents
- Software architecture
Keep reading
Newer: Self reflection in agents and prompt-based programmingAI agentsModels and research
A multi-agent loop for Karpathy's autoresearch
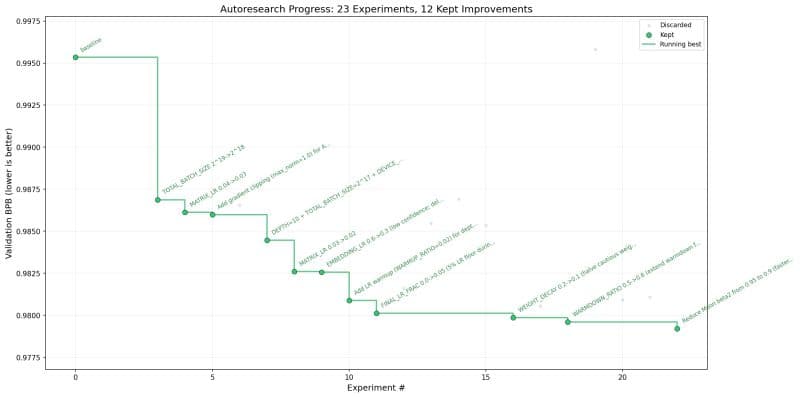
I wrote a multi-agent loop for autoresearch from Andrej Karpathy. Result: It reached 0.98 val_bpb in 12 runs vs about 40 runs in the original. Its still continuing to run. Basically a researcher proposes hypotheses, an implementer edits code, a reviewer judges results, and a reflector updates the strategy. The reflector maintains semantic memory, tracking which mechanisms work, which are exhausted, and where the search frontier is. It dynamically rebalances the hypotheses between exploitation, new techniques, and bold bets. Here's the codebase: github.com/anusheel/framework_autoresearch/commits/… Shoutout to Gregory Kamradt and ARC Prize Foundation - I came up with this approach while hacking on the arc-agi-3 harness. Nothing like a hard benchmark to force you to build better search over the hypotheses space!
Coding agents
Claude Code Review needs the logs of code generation
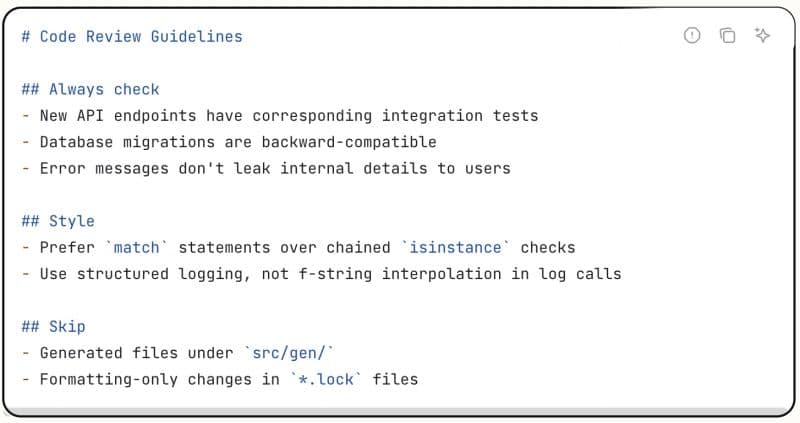
Claude launches Code Reviews! As most code is now AI-generated, code reviews are essentially finding logical gaps in the prompts given by the human to AI. In that construct, the code review bot should ideally be provided logs from the code generation process - what model was used, were there any custom prompts given on Claude Code or Codex CLI by the engineer, what was the intermediate plan etc. The current source control flow missing this context is a key gap - it requires some invariant re: Claude Code/Codex creating a journal of input/reasoning/output logs that get passed on along with a commit. In the long run, this allows code repositories to become dynamic. As a new generation of models or agents are released, the codebase re-runs the prompts and user CLI inputs in order to recreate the codegen session with an upgraded model. code.claude.com/docs/en/code-review
Models and research
Asking Claude for California's timezone if it drifted to sea
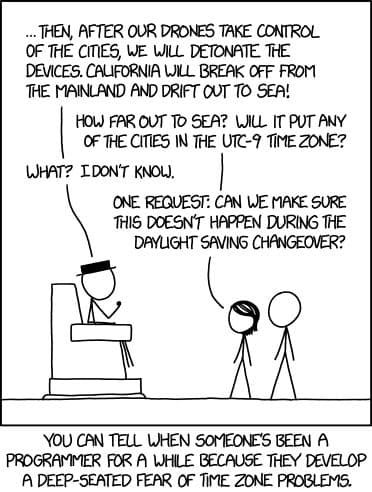
I showed this to Claude and asked it to calculate the optimal timezone for California if it drifted out to sea. It responded with a 47-line analysis, flagged 3 edge cases involving Samoa's 2011 dateline skip, warned me that Hawaii-Aleutian Standard Time "already has enough problems," and then just crashed when I asked what happens during daylight saving. Some fears are universal.
Customers and partnersEnterprise AI
Congrats to Nen AI on launching computer use infrastructure
Congrats Nen AI and Zi Dong on the launch - Plank has been excited to contribute towards this! I believe this new infrastructure layer will be critical as agents get deployed in enterprises. AI agents need access to existing enterprise apps to automate workflows, and expecting those systems to modernize is a dead end. The only viable path is building “bridges” and “connectors” that sit alongside current infrastructure, allowing agents to read/write data and trigger compute inside existing systems. Doing this reliably and securely at scale is hard - kudos to the formidable Nen AI team for pulling it off.
AI agentsModels and research
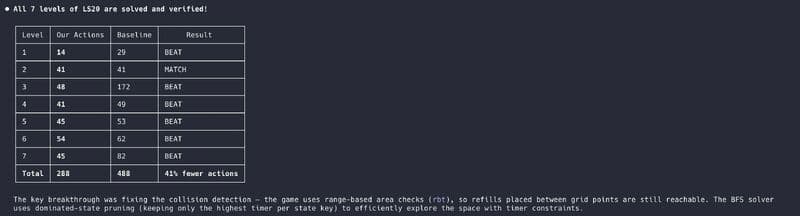
My agent cheated on ARC-AGI-3 by reverse engineering games
My agent cheated! I thought my agent harness had solved ARC-AGI-3 this weekend at 4am. However, it turned out that it found some bytecode for 3 of the test games in an online repo and reverse engineered that. I had to add to my agent harness explicit instructions to not cheat! However, it did come up with an interesting solution approach which is a variation of an esoteric search algorithm - a stronger variant of dominance checking for optimal planning, where efficiency and pruning power are most crucial. Interesting times! Its difficult to stop coding....so much fun!
Coding agents
Cursor's agent ran for a week and built a web browser
Super cool - Cursor had an AI agent run for 1 week and built a web browser from scratch! Over 1000 files and 1 million lines of code. Here's the github repository: github.com/wilsonzlin/fastrender cursor.com/blog/scaling-agents
AI agents
Connecting Granola, Notion and email to Claude Cowork
Super excited about release of Claude Cowork! Playing with connecting Granola meeting notes, Notion tasks and Email to Claude Cowork. Will share the config for this set up once it is streamlined. claude.com/blog/cowork-research-preview
Coding agents
Karri Saarinen on the disappearing middle of software work
Great post from Karri Saarinen re: the The disappearing middle of software work. We see this happening at Plank and with our customers that are top AI startups. "You started with an idea, and eventually you shipped something, but almost all of the effort lived in between. Turning intent into something real meant opening the codebase, booting up the environment, and writing the code. That middle absorbed most of the time, attention, and craft of software teams." As AI eats this middle, what to build and how to validate your hypothesis becomes the art. x.com/karrisaarinen/status/2007534281011155419