LlamaIndex dynamic section retrieval improves RAG results
Good work @llamaindex - this approach solves some key problems with RAG around:
- retrieving entire contiguous sections vs fragmented chunks
- attaching metadata to sections and being able to use that metadata in retrieval
We are already seeing improved results (and a simpler codebase) in a few use cases here at Plank
We’re excited to feature a new RAG technique - dynamic section retrieval 💫 - which ensures that you can retrieve entire contiguous sections instead of naive fragmented chunks from a document.Read LlamaIndex’s full post on LinkedIn
- Software architecture
Keep reading
Newer: LLMs learn by compression, as Ilya Sutskever arguesSoftware architecture
Missing DTrace from Solaris for tracing live processes
I miss dtrace from Solaris. Dtrace probes would allow you to attach the trace to live running processes, without needing to restart the process. Some things you could check: - print which functions are doing memory, disk allocation or network requests incl the sizes. This was great to catch memory leaks or programs with poor cache performance - trace a specific code function. Using the symbol for the function in the binary, you could print the parameters and function return values - trace the latency of a user request by tracing invocations of functions at the start/end of the processing - performance measurement of modules. Attach the probe for an hour and do a running count of how many times a function was called or how much memory was used on average for a request Linux strace seemed not as powerful. Any other options? brendangregg.com/dtrace.html
Models and researchSoftware architecture
Quantized Llama models make on-device AI apps practical
With the latest quantized Llama models that are just 1.3GB and 3GB in size, you can start doing mobile/desktop apps that download fine tuned models per user/customer and can run fully locally. This makes variable running costs of AI apps zero and moreover achieves maximal data privacy. We are building a few apps with this new awesome architecture. Anyone else doing that? Would love to exchange notes.
Software architecture
When RAG and vector databases are the wrong tool
Common error in app-layer LLM products is that people use RAG and Vector DBs incorrectly. To process a single document or small amount of input information, people first chunk it, throw it in a vectorDB then retrieve it and put in the context. That makes no sense if the original document is small and could literally be fully packaged in the context window. Remember - you need RAG if during inference, you need to select a subset of information from thousands of documents (100s of millions or billions of tokens), which of course is impossible to include in the context window of a single inference.
Software architecture
Eras of software from the mainframe age to AI
I've been reflecting on the evolution of software development and the distinct eras the industry has experienced over the years. For each era, I've considered the defining characteristics, the technological advancements that emerged, and the market segments most affected or newly created by these innovations. Dive deeper into this exploration on how software has transformed from the mainframe age to today's AI-driven landscape. In a follow-up post, I will talk about how the tooling has evolved from assembly languages to high-level languages to now plain-english prompts and agentic pipelines.
Software architecture
The tech and people stack you need for your AI startup
Hi friends, in continuation of our discussion on best practices in software architecture, today's focus is on the essential tech and people stack for your AI startup. Dive deeper into the tech stack with us and stay tuned for a follow-up post on the people and team structure aspect. Read more about the crucial elements for your AI startup here:
Software architecture
Why the ZIRP era ruined software architecture
Hi friends, I'm excited to kick off a series of posts on the latest best practices in software architecture. To begin, let's delve into a brief history of how things have evolved over the past 10 years
Coding agents
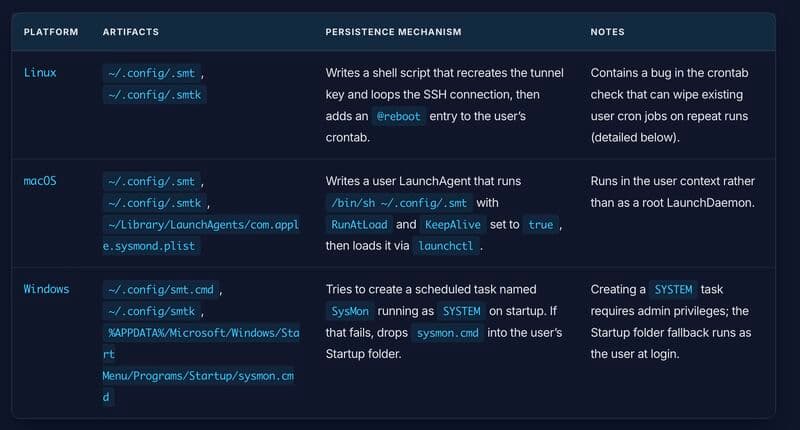
Phorion finds a backdoor in Claude Code's VS Code extension
Phorion has detected a backdoor in the official Claude Code for VS Code extension bundle on the Cursor Marketplace that drops a persistent SSH backdoor across macOS, Linux, and Windows! Could this be behind the Binance hack? phorion.io/blog/offical-claude-code-vsx-compromise
Customers and partnersAI agents
Congrats to Mintive on its fundraise for AI agent identity
Congrats to Mintive on the fundraise - rockstar team. The Plank FDE team has loved partnering with the Mintive product team to help get this deployed in enterprises in a safe/secure way.