Day 3

The AI SDLC: feature development workflow

You ship
A Linear backlog, with its first tickets shipped through the full loop toward 10 pull requests an hour.

What you'll build today

After Day 2, Claude Code knows your project's routines, and its 3 reviewers have read your Day 1 code. WorkBot itself still does nothing for its users, and the work ahead lives only in your head, where Claude Code cannot see it.

Today you run the AI software development life cycle (SDLC) from ticket to deployment. You write the work down first, as a backlog of small tickets in Linear, each with acceptance criteria that say when it is done. Then you connect Claude Code to Linear, GitHub and Figma through the Model Context Protocol (MCP), a standard way to give AI tools access to other systems. Claude Code can then read a ticket itself, without you pasting it.

With that in place, you ship WorkBot's first real feature. People file a request, a piece of work for a team such as operations, finance or support, and find it in a list, an API and an admin overview. You write the specs and review, and Claude Code implements. By the end, 7 tickets are merged and live on production.

By the end of the day you can

  • Run the full AI software development life cycle (SDLC): Linear ticket, Figma design, code, test, pull request, deploy, monitor
  • Connect Claude Code to Linear, GitHub and Figma through MCP (Model Context Protocol) servers
  • Write feature specs clear enough for AI to implement from
  • Work toward 10 pull requests an hour through the full SDLC loop

Topics

The AI SDLC Flow

  • The traditional SDLC against the AI SDLC: what changes when AI writes most of the code
  • The new flow: Linear ticket, Figma design, code, test, pull request, deploy, monitor
  • Where humans add the most value: writing specs, reviewing, making architecture decisions, finding edge cases
  • Where AI adds the most value: implementation, test generation, boilerplate, refactoring

MCP Integrations

  • Linear's MCP server: read tickets, update their status, and pull acceptance criteria straight into Claude Code's context
  • GitHub's MCP server: create branches, open pull requests, read review comments, manage issues
  • Figma's MCP server: read design specs, and extract a component's dimensions, colors and layout
  • Configuring a project's MCP servers in .mcp.json at the repository root

Writing Effective Specs

  • What makes a spec good for AI implementation: clear acceptance criteria, explicit constraints, examples
  • Spec templates: a feature spec, a bug fix spec, a refactor spec
  • Anti-patterns: vague requirements, implicit assumptions, missing edge cases
  • The spec, implement, review loop: how to improve the result on each pass

Review-Driven Development

  • You write the spec, AI implements it, and you review and iterate
  • What to check in AI-generated code: correctness, patterns, security, performance
  • When to refine the spec, and when to edit the code directly
  • Practicing review until it becomes a habit

Build

Features shipped today

  • WorkBot: A Linear workspace with its first 15 to 20 tickets. The first ones go through the SDLC loop: the request data model, an intake form, a requests list, a requests API, and an admin console shell with an overview

Set up Linear with a backlog of 15 to 20 small feature tickets for WorkBot. Give each ticket:

  • Clear acceptance criteria
  • A Figma design reference, where the ticket has a screen
  • An estimated size, small or medium

Run the full AI SDLC loop on each ticket:

  1. Pick a Linear ticket
  2. Read its Figma design through the Figma MCP server
  3. Write or refine the spec
  4. Let Claude Code implement it
  5. Review the result, and iterate if needed
  6. Run the tests
  7. Open a pull request
  8. Deploy

Target: 10 pull requests an hour. The goal is to make this workflow a habit.

Step by step

Fix the review findings

Day 2 ended with the review trio's findings on your Day 1 code, so your first pull request today acts on them. In the reference run, the review found the issues fixed below. Your review may differ, so fix what yours found.

Study first

  • Sort the findings into 3 groups: fix now, fix later with a ticket, or disagree with a reason. Google's code review guide covers handling reviewer comments, including how to disagree by explaining the tradeoffs. Its page for reviewers on handling pushback says to file a ticket for a cleanup that cannot happen now, so it does not get lost.

Build

  1. Make the health route answer from the running server. Call await connection() from next/server before reading the configuration, so Next.js no longer prerenders the route.
  2. Commit the smaller fixes together. Use || instead of ?? for environment fallbacks, so an empty variable falls back too, and add !.env.example and *.log to .gitignore. Move shadcn and tw-animate-css to devDependencies, and remove the unused Separator component. Set permissions: contents: read in the CI workflow, which limits the workflow's token as GitHub's permissions guide describes.
  3. Open the pull request with the findings listed, one line each, so anyone can trace each fix back to a reviewer's finding.

Done when

  • pnpm build lists /api/health as dynamic, which means it renders on each request, and the pull request is merged with CI green.
Technical notes
  • Under Cache Components, the rendering model from Day 1, Next.js prerenders a GET route handler like a page. It stops only when the handler reads request data or calls connection(), which the Next.js reference describes. A prerendered health check reports the values from build time.
  • ?? falls back only on null and undefined. With VERCEL_GIT_COMMIT_SHA="", WorkBot would have shown an empty commit, while || treats the empty string as missing too.
  • create-next-app writes .env* into .gitignore, which also ignores .env.example. That file documents the variables and must be committed, so un-ignore it by name.
Start a backlog in Linear

With the old findings closed, the next step is to write down the new work before anyone builds it. Each ticket gives Claude Code acceptance criteria to implement, and the review of its pull request then checks the change against them. Linear is the issue tracker the course uses.

Study first

  • Linear's conceptual model. Linear calls a ticket an issue, and each issue has a project, a status, labels and an estimate.

Build

  1. Create the Linear workspace and 20 tickets for the features of Days 3 to 5. Linear names each ticket with a team key and a number. In the reference run the key is WB (for WorkBot), and WB-1 to WB-4 record Day 1's features as done, so today's work starts at WB-5.
  2. Give each ticket a title, 2 to 4 acceptance criteria, and a size, where S means under an hour and M means 2 to 4 hours. Where a ticket has a screen, attach its Figma frame, which is Figma's name for the design of one screen.
  3. Copy the tickets into docs/backlog.md, so a Claude Code session can read a ticket by its path.

Done when

  • The 20 tickets are in Linear with their criteria and sizes, and docs/backlog.md holds the same tickets.
Technical notes
  • The backlog copy is a Markdown table, plus a section of criteria for each ticket.
  • Put the ticket id in a commit subject, such as (WB-6), to link the commit to its criteria. Ticket ids go in commit subjects only, never in code.

Connect the MCP servers

A backlog helps most when Claude Code can read it without you pasting tickets into the prompt. An MCP server gives Claude Code access to one outside tool, such as Linear, through the Model Context Protocol. With 3 servers connected, Claude Code reads a ticket, a design or a pull request on its own.

Study first

Build

  1. Add .mcp.json with the Linear, GitHub and Figma servers over HTTP, using the entries in the technical notes.
  2. Start Claude Code, run /mcp, and sign in to each server.
  3. Ask Claude Code for a ticket's acceptance criteria by its Linear id, for the frame attached to a ticket, and for what changed in your Day 1 pull request.

Done when

  • Claude Code reads a ticket from Linear, a frame from Figma and a pull request from GitHub, without you pasting any of them.
Technical notes
  • The 3 entries in .mcp.json look like this:
{
  "mcpServers": {
    "linear": { "type": "http", "url": "https://mcp.linear.app/mcp" },
    "github": { "type": "http", "url": "https://api.githubcopilot.com/mcp/" },
    "figma": { "type": "http", "url": "https://mcp.figma.com/mcp" }
  }
}
  • A project's MCP servers live in .mcp.json at the repository root, and you commit that file, while Claude Code stores the sign-in tokens outside it. .claude/settings.json holds hooks and permissions, not servers.

Ship 7 tickets through the loop

With the backlog readable from Claude Code, you can run the full loop on real features. For each ticket, create a branch, write the brief for Claude Code from the ticket's criteria, and let Claude Code implement it. Then review the change, run the tests, and open and merge the pull request, which deploys it. The curriculum's target for the day is 10 pull requests an hour.

Study first

  • Server Actions and React's useActionState. A form posts to a function on the server, and that function returns the next state, such as field errors, or redirects.
  • Zod 4's z.object, .safeParse, z.flattenError, and z.infer for the type, all in the Zod API reference.
  • React's Suspense under Cache Components. A component that reads changing data runs at request time, inside a Suspense boundary with a fallback, and io() from next/cache marks that read.

Build

  1. WB-5 adds the request data model. Write a Zod schema for a request, with a title, details, a team and a priority, and export its inferred type. Keep the requests in a list in memory, shared through globalThis, and add createRequest and listRequests with unit tests for trimming, defaults and rejection. In your brief, turn each acceptance criterion into a sentence a test can check.
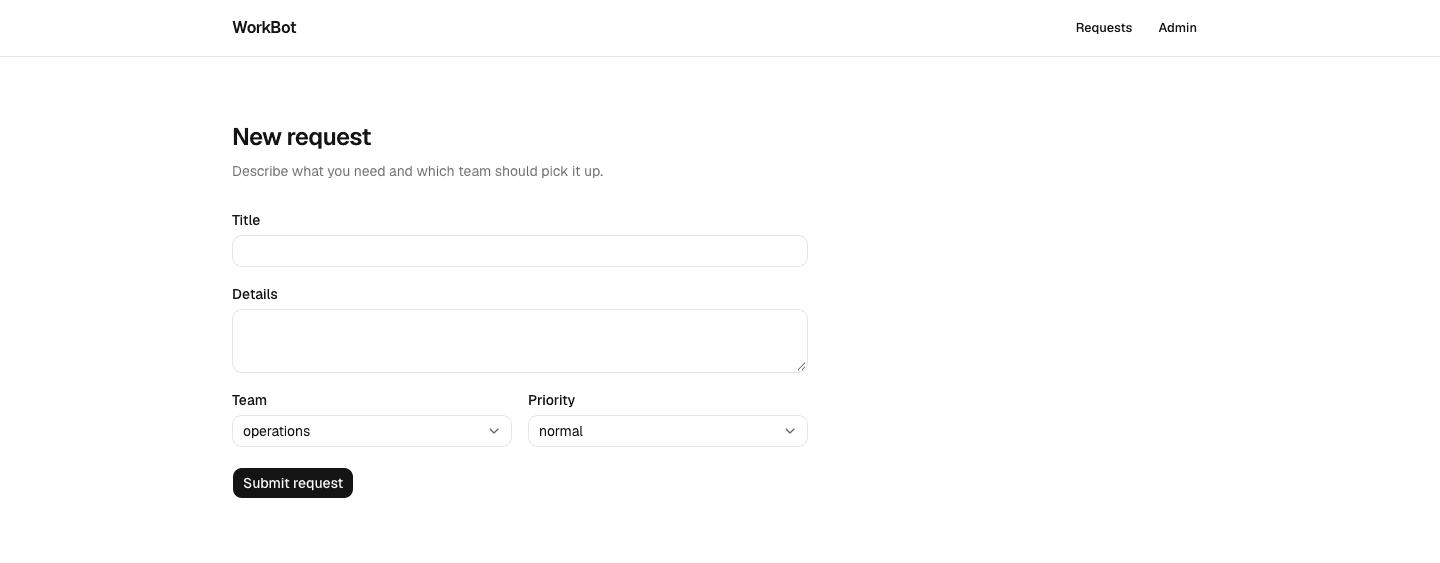
  2. WB-6 adds the intake form. Build /requests/new with Input, Textarea and NativeSelect from shadcn/ui, and submit it through a Server Action that returns field errors or redirects to the list.
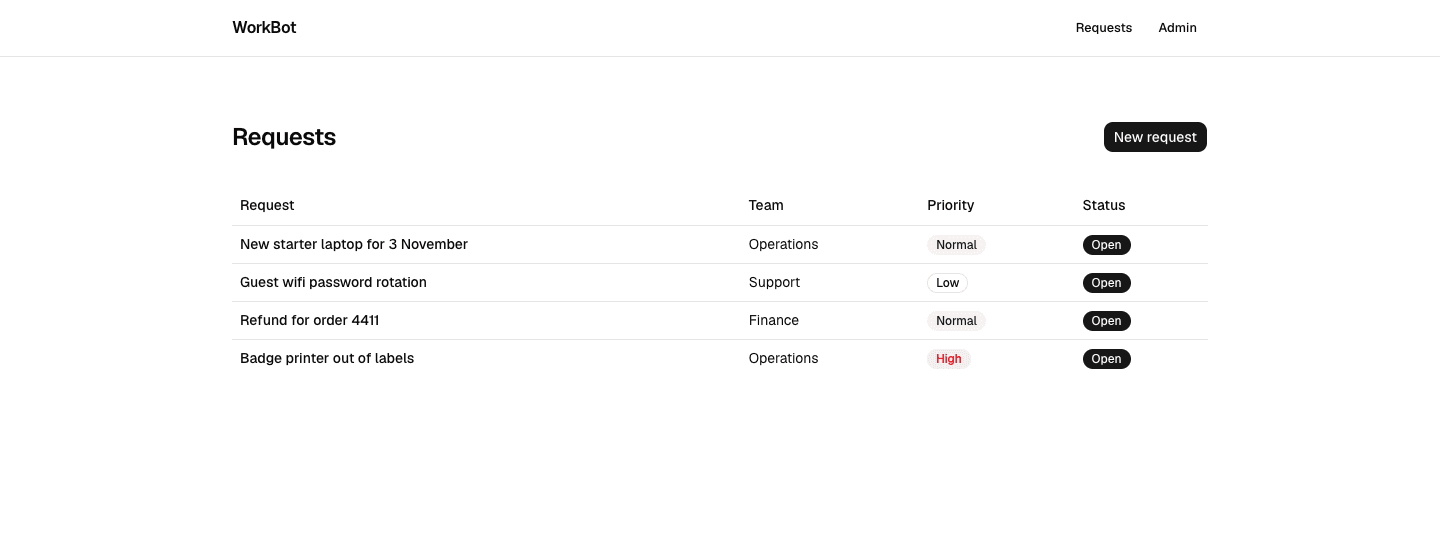
  3. WB-7 adds the list. Build /requests as a Table, with badges for priority and status, an empty state, and a button to the form, and link to it from the header.
  4. WB-8 adds the API. Write GET and POST /api/requests, validated by the same schema, with tests that parse every response through a response schema.
  5. WB-9 and WB-11 add the admin shell. Give /admin a layout with side navigation, and move the settings page to /admin/settings.
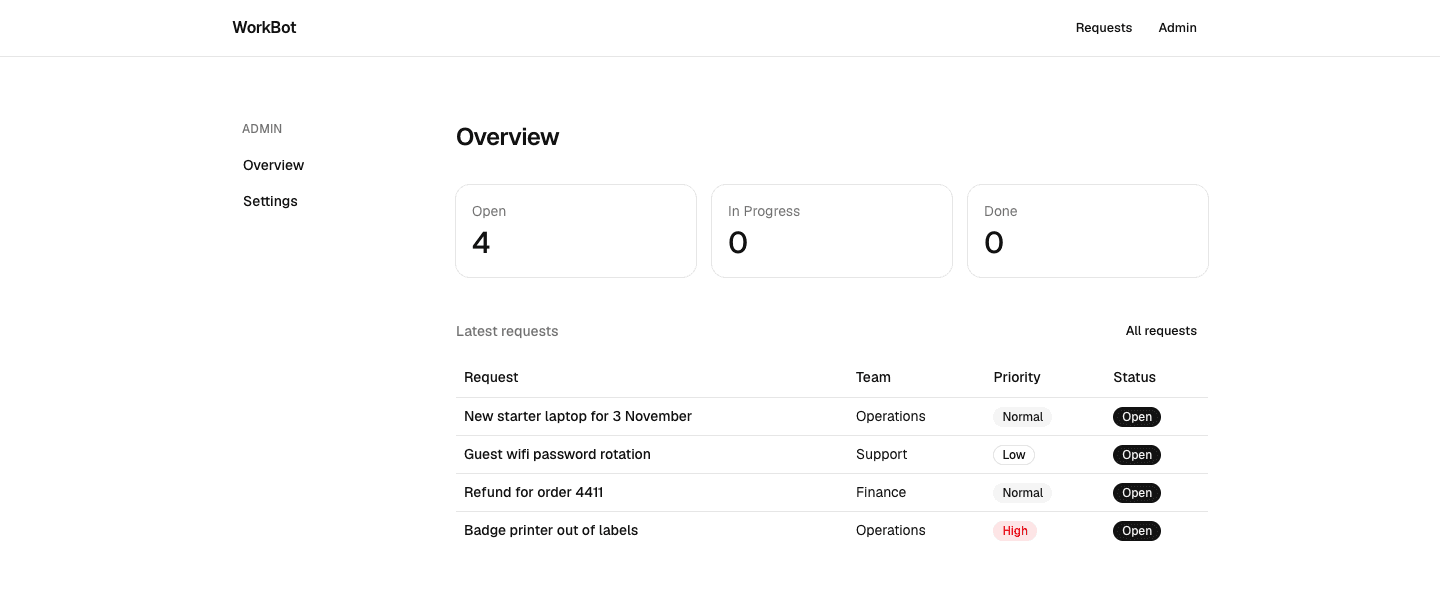
  6. WB-10 adds the overview, which shows a card for each status with its count, and the 5 latest requests.
  7. After each merge, open the production URL and use the feature once.

Done when

  • A request filed on the production form appears on the list, in the API's GET response, and in the admin overview's counts.
The intake form
The intake form. The schema's lists fill the selects, and each error from the Server Action shows under its field.
The requests list
The requests list, newest first, with priority and status as badges.
The admin overview
The admin console shows the counts per status and the latest requests, and now holds the settings page.
Technical notes
  • One schema serves 3 uses. The Server Action parses FormData with it, the API parses JSON with it, and the request type derives from it.
  • The Server Action returns { errors } from z.flattenError(error).fieldErrors, so each field shows its own message. On success it calls redirect, which throws, so nothing after it runs.
  • Use native selects rather than shadcn's Select, which is built on Radix, so the form submits without JavaScript. The pending state from useActionState is an enhancement on top.
  • Next.js bundles each route on its own, so a module-level array would give one list per route, while globalThis holds a single list within one server process. A restart loses that list and a second instance would not see it, which is why the database arrives on Day 5.
  • listRequests awaits io() from next/cache, which tells Next.js that request-time work follows. During prerendering it suspends, so the Suspense fallback goes into the static shell and the list renders on each request.
  • The API's tests call the exported GET and POST with a Request object, so no server runs. The response schema in types.ts is what client code would validate against.

Resources